

Overview
In this tutorial, you’ll learn how to add custom evaluations to a comedy multi-agent LLM app using Splunk Agent Observability. This tutorial is intended for Python developers building domain-specific AI applications. It assumes you have basic knowledge of:- Some familiarity with Python/Flask
- Python Package Manager of choice (we’ll be using uv)
- Code editor of choice (VS Code, Cursor, Warp, etc.)
- API keys for:
- OpenAI, NewsAPI (free!), and Splunk Agent Observability (free!)
- Understand the importance of domain-expertise in Splunk Agent Observability
- Create a custom LLM-as-a-Judge evaluator to measure outputs
Background
For the sake of jumping right into action — we’ll be starting from an existing application and demonstrating how to add custom evaluators to an existing application. The app we’ll be building off of is the Startup Sim 3000, an LLM-based Python application that generates either serious or silly startup pitches using OpenAI and real-time data. The app includes two agent chains:- Serious Mode: Uses NewsAPI data and GPT-4 to generate business-style startup pitches
- Silly Mode: Uses HackerNews headlines to inspire parody pitches of absurd tech startups
Create a new Splunk Agent Observability project
In order to set up custom evaluators, we’ll need a Splunk Agent Observability project to log evaluations to first.1
Create a new project from the Splunk Agent Observability UI
If you haven’t already, log into Splunk Agent Observability and create a account. When prompted, add an organization name.Create a new project by clicking on the Create new project button on the upper right hand screen. You will be prompted to add a project name, as well as an Agent Stream name.
For more information on getting started, see the Quickstart.
2
Get your Splunk Agent Observability API Keys
Click on the profile icon in the upper right hand side of the page, navigate on the drop-down menu to API keys.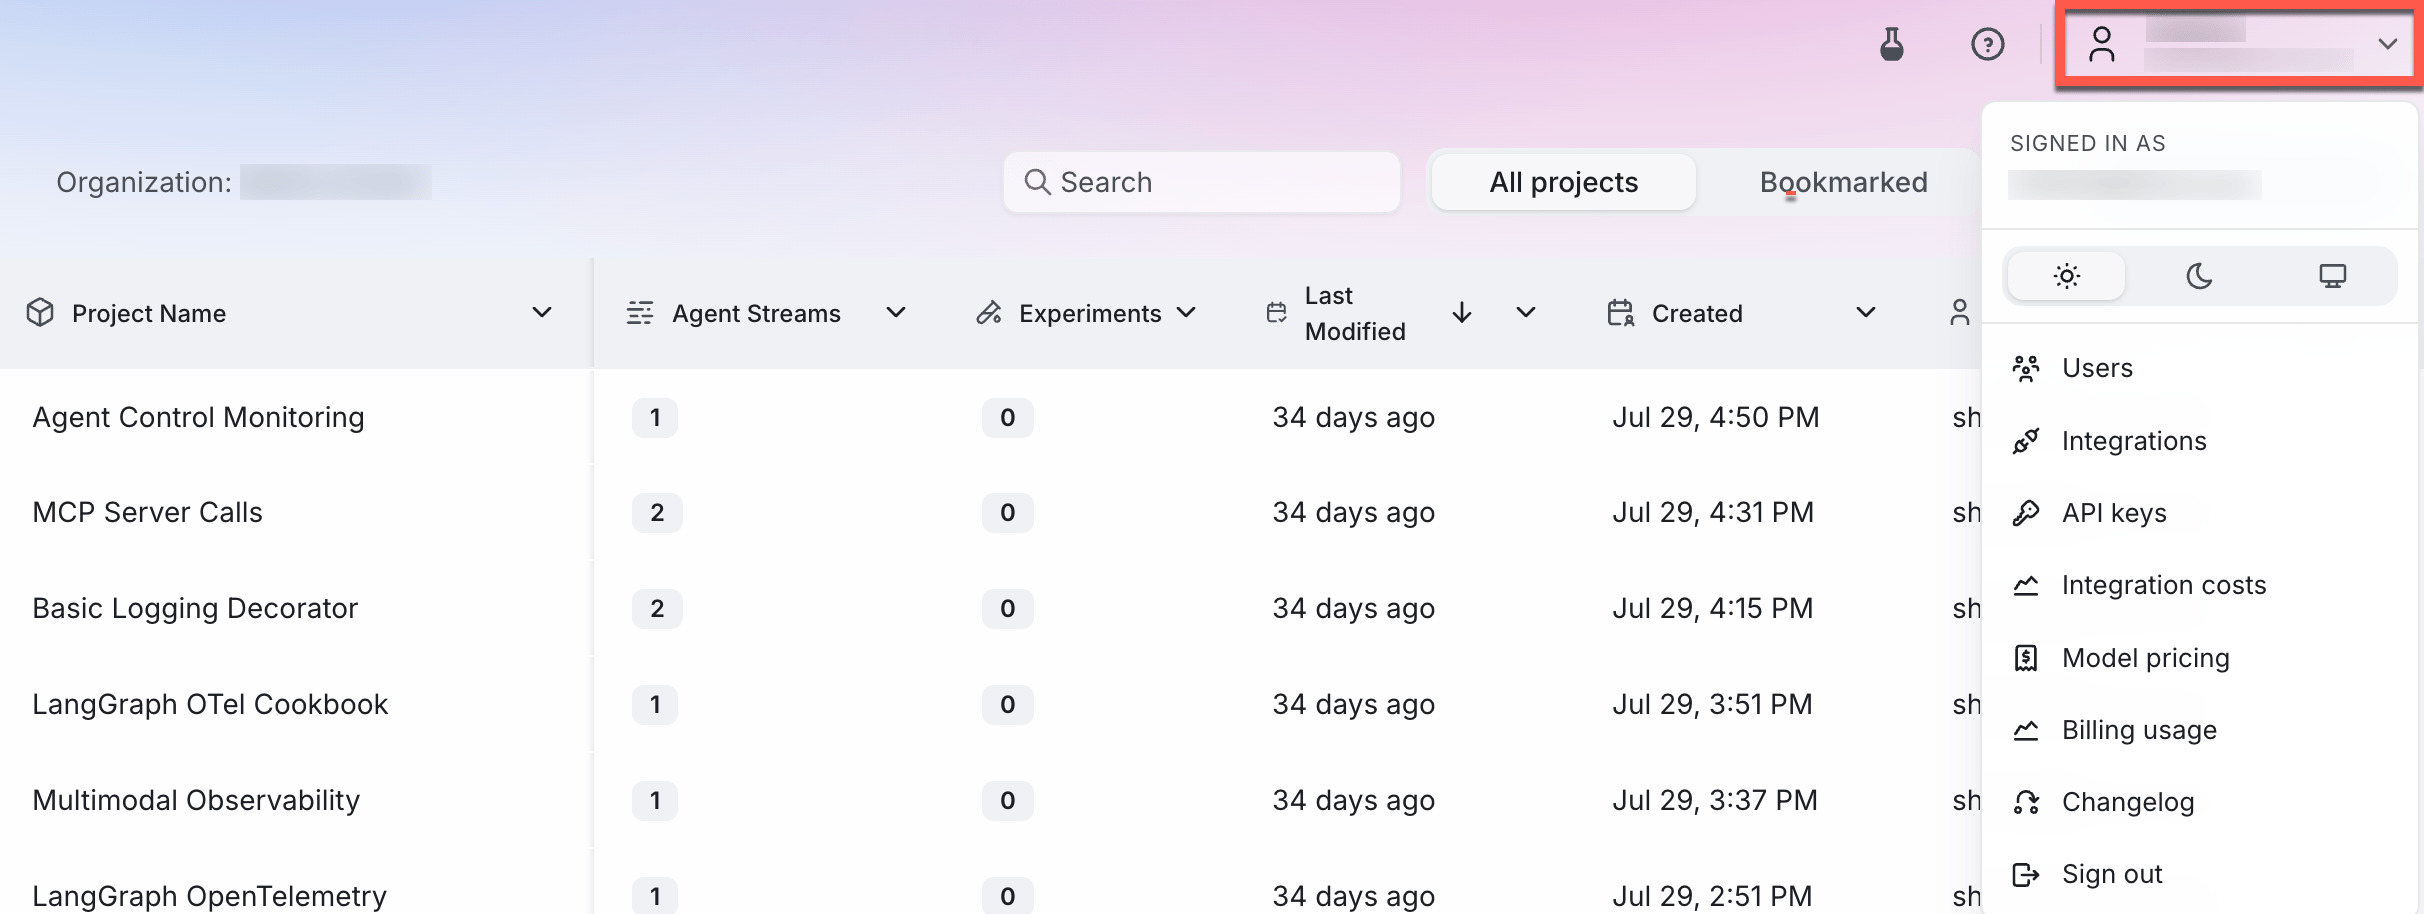
Set up the project
1
Clone the project in your IDE of choice.
The starter project is in the
examples/agent/startup-simulator-3000 folder in the cloned repo.2
Set up a virtual environment and install dependencies.
A virtual environment keeps your project’s dependencies isolated from your global Python installation. For this we’ll be using uv.On Windows:On MacOS/Linux:This creates and activates a virtual environment for your project, then installs the necessary requirements.
3
Configure your .env file.
Take the
.example.env file, copy it, renaming it to .env and add in your own variables. Be sure the variables are added to your .gitignore file.When complete, it should look something like this:.env
4
Start the Flask app and test out the application
After your environment variables are set, you are all set to run the application. The application is designed as a Flask Application, with a JavaScript frontend, and Python backend.Run the application locally by running the following in the terminal.Your application will be running at http://localhost:2021 — open that within your browser and start exploring.Try generating both “Silly” and “Serious” mode pitches.The standard flow of the application is as follows:
User Input → Flask Route → Agent Coordinator → Tool Chain → AI Model → Response
Create a custom LLM-as-a-Judge evaluator in Splunk Agent Observability
1
Add Evaluators to your Agent Stream in Splunk Agent Observability
Navigate to your project home inside of Splunk Agent Observability. Select the Agent Stream you’ve got your traces in.Click on the Trace tab and see your most recent runs listed below.From this view, navigate to the upper right hand side of your screen and click on the Configure Evaluators button. A side panel should appear with a set of different evaluators from you to choose from.
2
Add custom Evaluators
That’s where custom evaluators come in.Once in this panel, navigate to the Create Evaluator in the upper right hand corner of your screen, and select LLM-as-a-Judge Evaluator.
3
Create your own LLM-as-a-Judge prompt
A window will appear where you will be able to generate an evaluator prompt. An evaluator prompt is a prompt to prompt the creation of the final LLM as a judge prompt. This is to ensure you spend your time focused on what’s important (the success criteria) instead of worrying about the output format.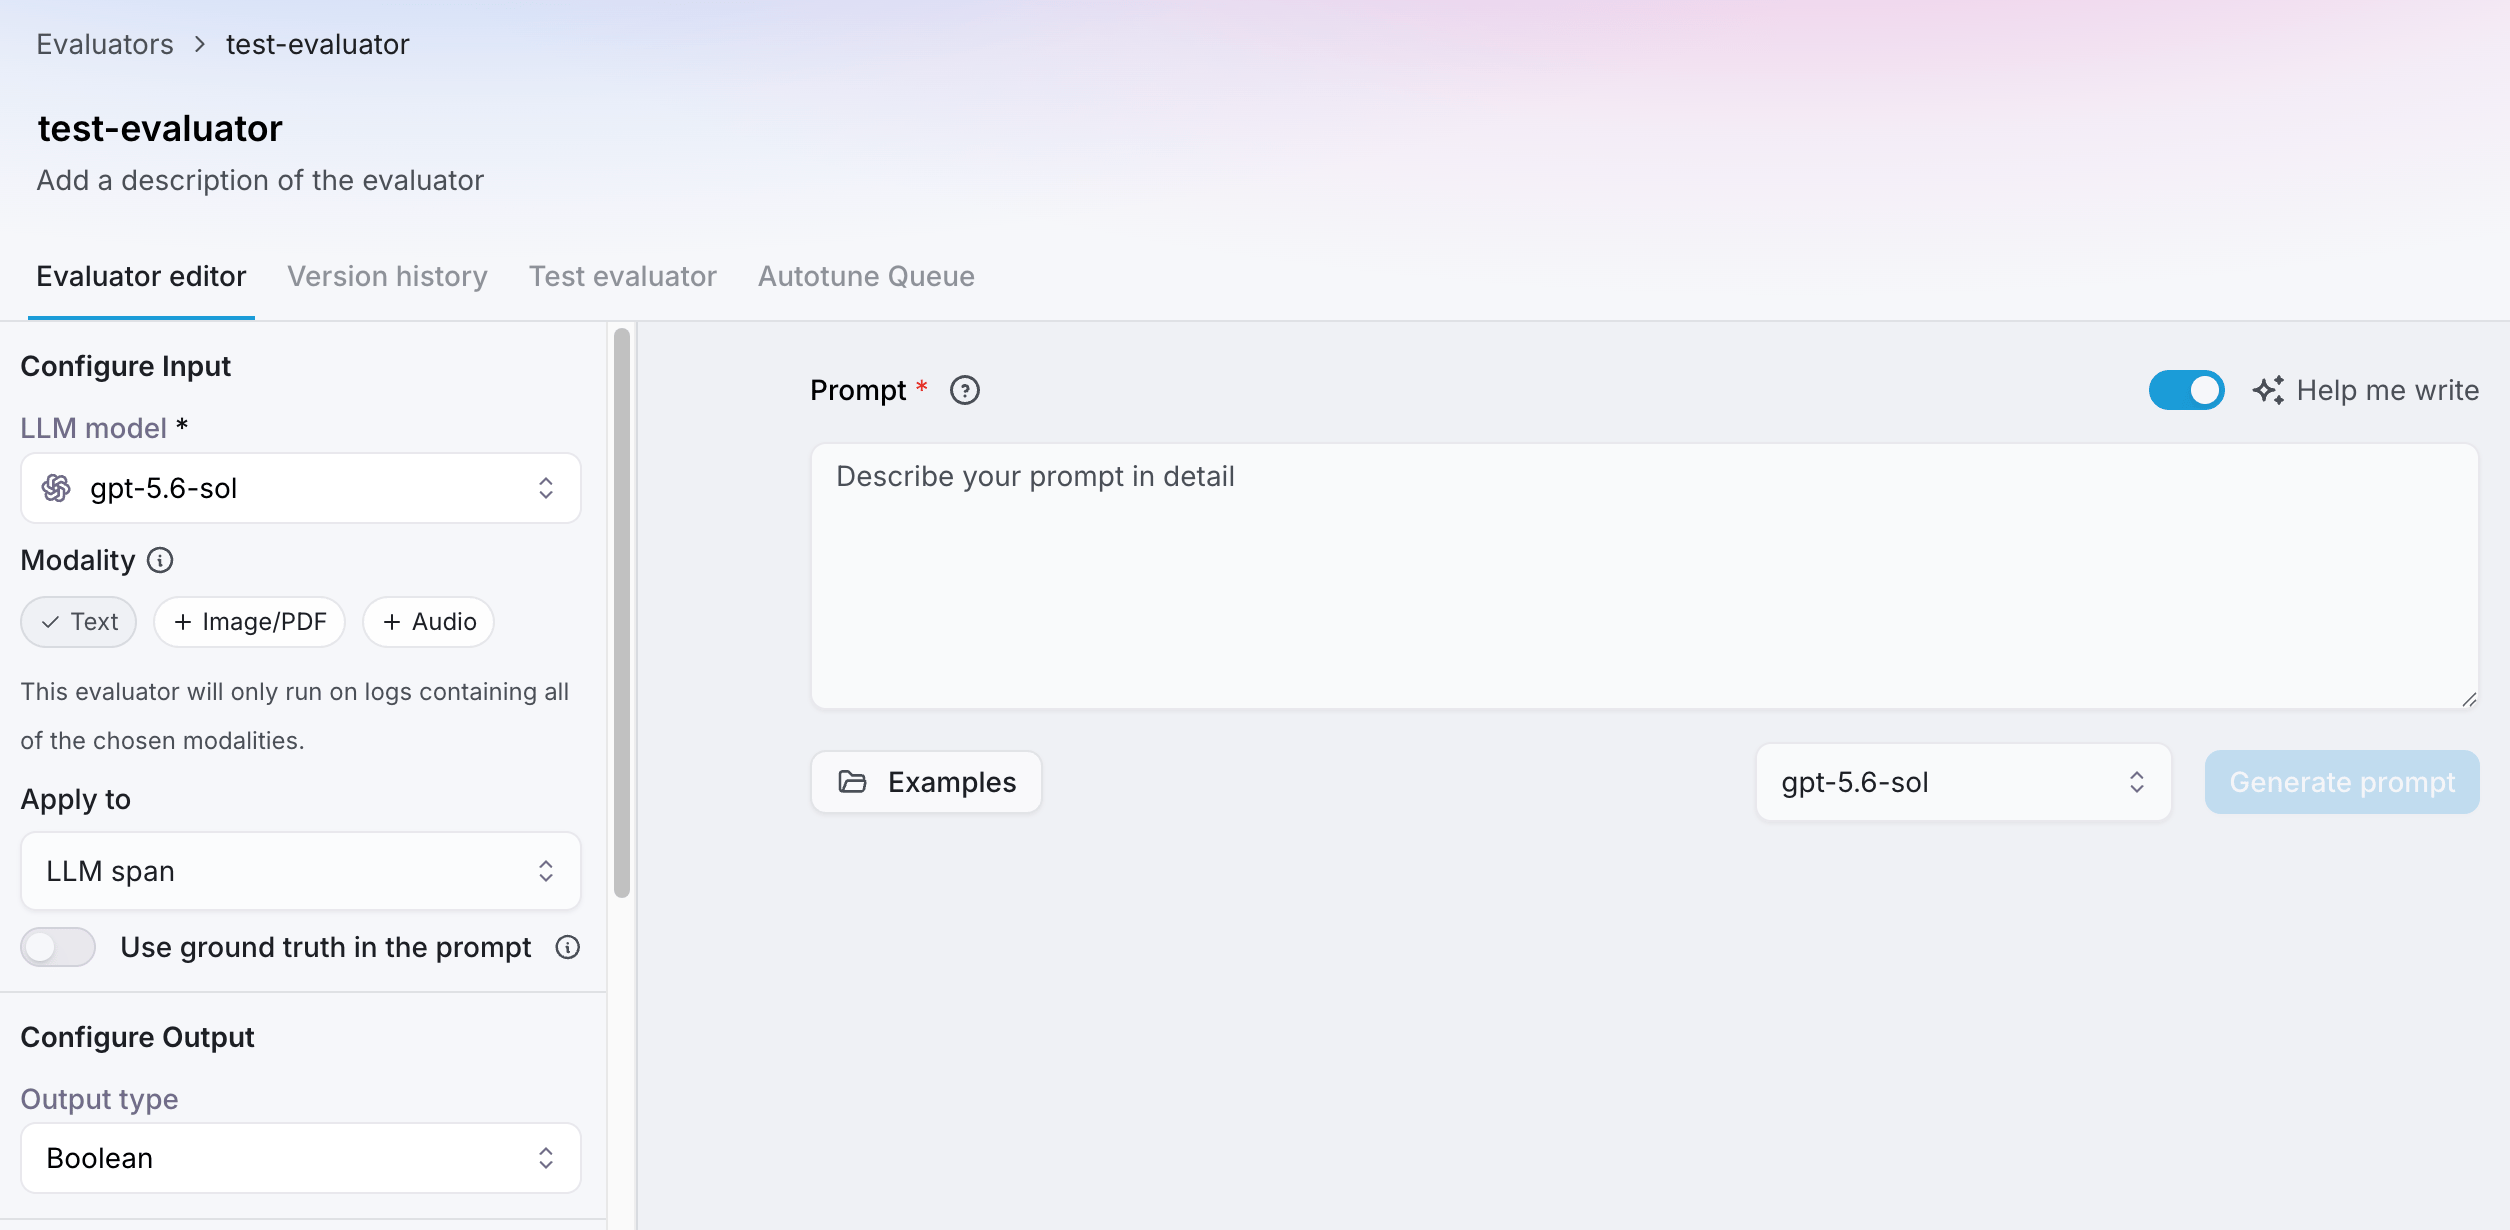
4
Test your evaluator
From within the Custom Evaluator pane, select Test Evaluator.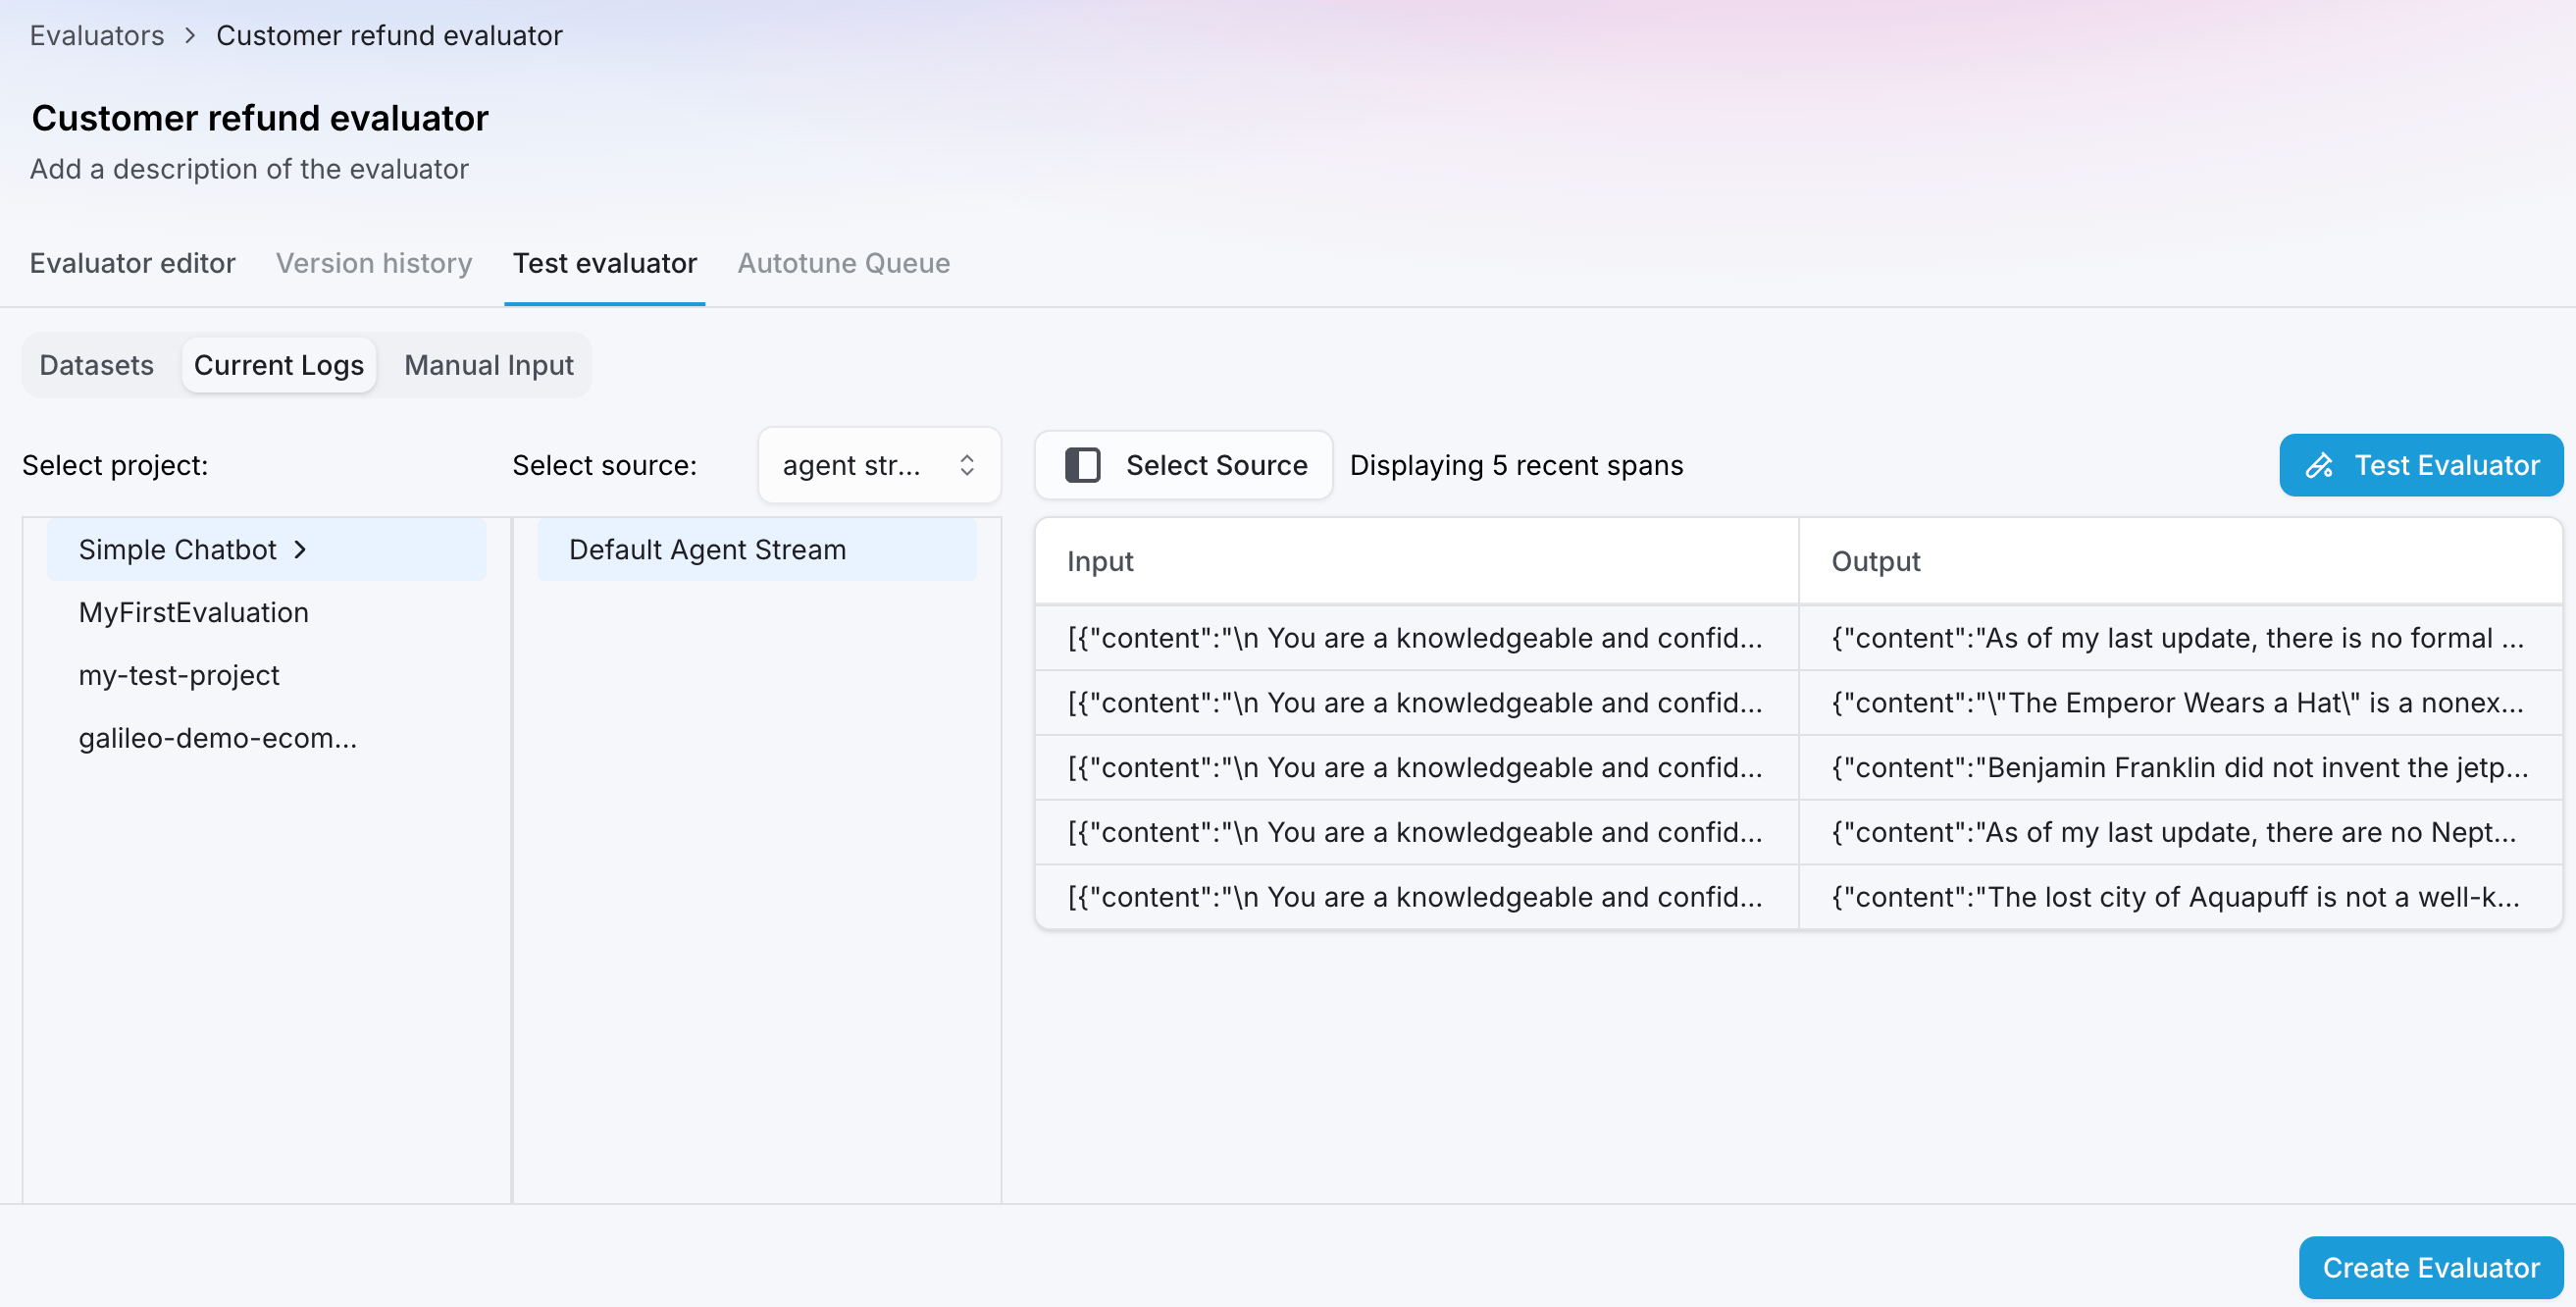
5
Add your Custom Evaluator
Once tested, your evaluator will appear in the list of available evaluators. Click on Configure Evaluators and flip the toggle the evaluator you’ve created, on. From there, it can be used to assess future LLM outputs across runs and sessions—giving you visibility into quality over time.
Summary
In this tutorial, you learned how to:- Configure and observe spans in a creative AI agent app
- Translate your domain expertise into a measurable AI quality rubric
- Build a custom evaluator with LLM-as-a-Judge to evaluate startup pitches
Next steps
- Check out other cookbooks in the Splunk Agent Observability cookbook library
- Explore how to create custom evaluators in Splunk Agent Observability using code
- Learn more about the different out-of-the-box-evaluators available in Splunk Agent Observability