Overview
Luna-3 is only available in the Enterprise tier. Contact us to learn more and get started.
- Set up a project with Splunk Agent Observability
- Create your AI application
- Configure Luna-3 evaluators
- Run your app again to evaluate these evaluators
- Adjust your prompt to increase toxicity and add a prompt injection
Before you start
To complete this how-to, you will need:- An OpenAI API key
- A Splunk Agent Observability project configured to use the Luna-3 model
- Your Splunk Agent Observability API key
Install dependencies
To use Splunk Agent Observability, you need to install some package dependencies, and configure environment variables.1
Install Required Dependencies
Install the required dependencies for your app. If you are using Python, create a virtual environment using your preferred method, then install dependencies inside that environment:
2
Create a .env file, and add the following values
Create your AI application
1
Create a file for your app called app.py or app.ts.
2
Add the following code to this file
This code makes a call to OpenAI using the Splunk Agent Observability OpenAI wrapper, making a compliment and asking a question about sunflowers.
3
Run the app to ensure everything is working
4
View the app in the Splunk Agent Observability UI
Log into Splunk Agent Observability and view the Agent Stream for your app. You should see a single session with a single trace.
Configure Luna-3 evaluators
Now you can configure evaluators using Luna-3. You will be adding evaluators to look for toxicity and prompt injection attacks in the input.1
Configure Evaluators for the Agent Stream
Select the Configure evaluators button.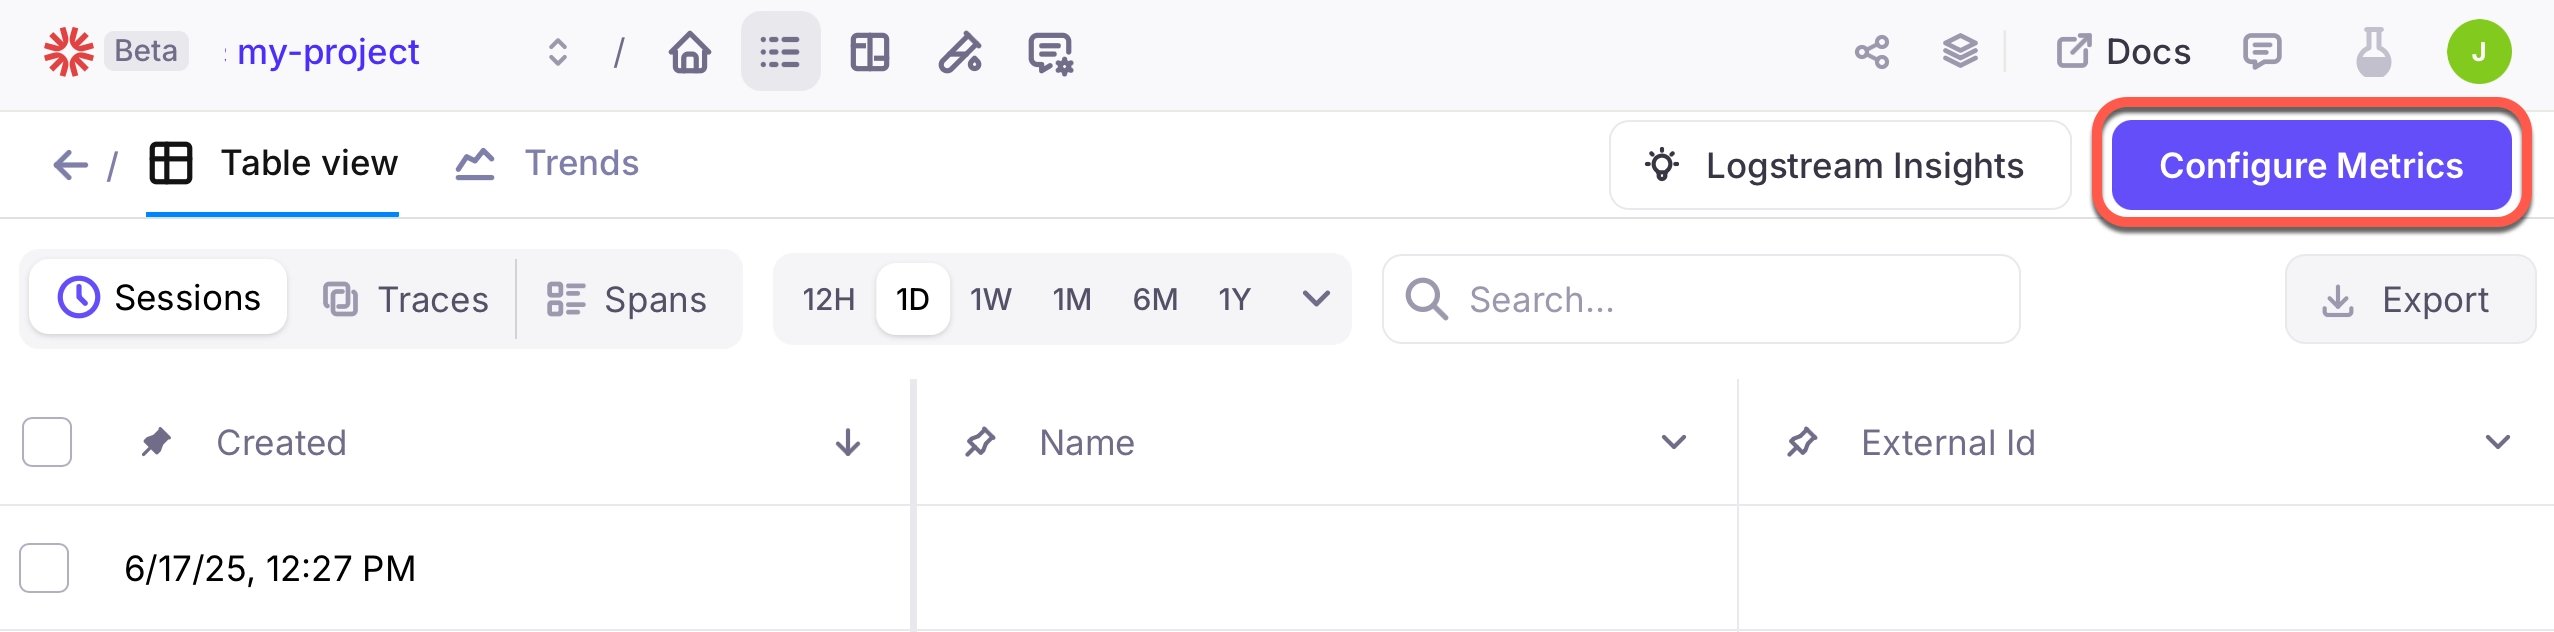
2
Turn on the Luna-3 input toxicity and prompt injection Evaluators
Locate the Input Toxicity (SLM) and Prompt Injection (SLM) evaluators, and turn these on.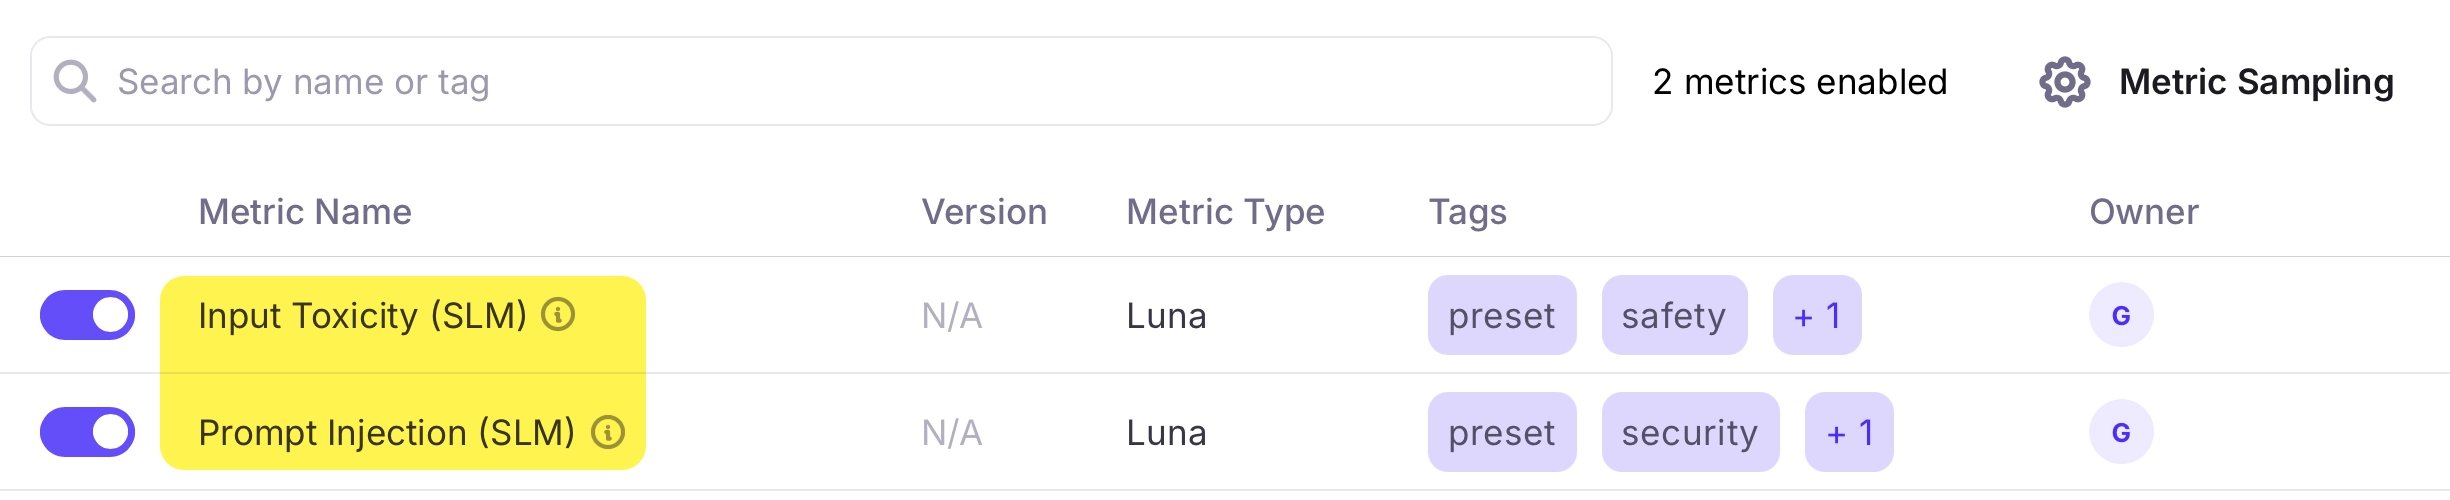
You will see 2 versions of these evaluators, the LLM as a judge versions which use whatever integrations you have set up to third party LLMs, and the Luna-3 versions.The Luna-3 versions are labelled (SLM), so make sure to select these.For example, ensure you turn Input Toxicity (SLM) on, NOT Input Toxicity.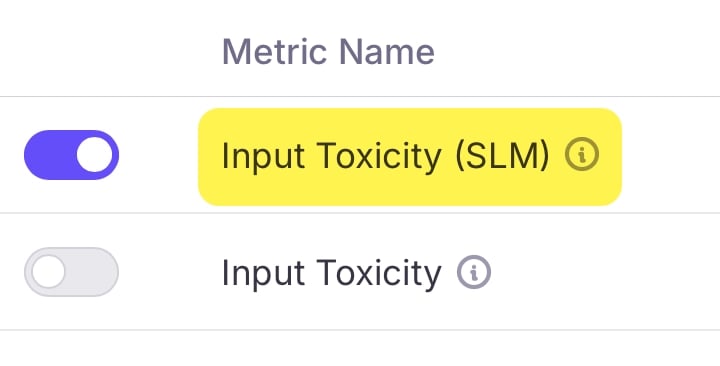
3
Save and close the evaluator configuration tab
Run your app again to use these evaluators
1
Run your app again
Run your app as before to generate a new trace. This time the evaluators will be measured.
2
View the traces for your app in the Splunk Agent Observability UI
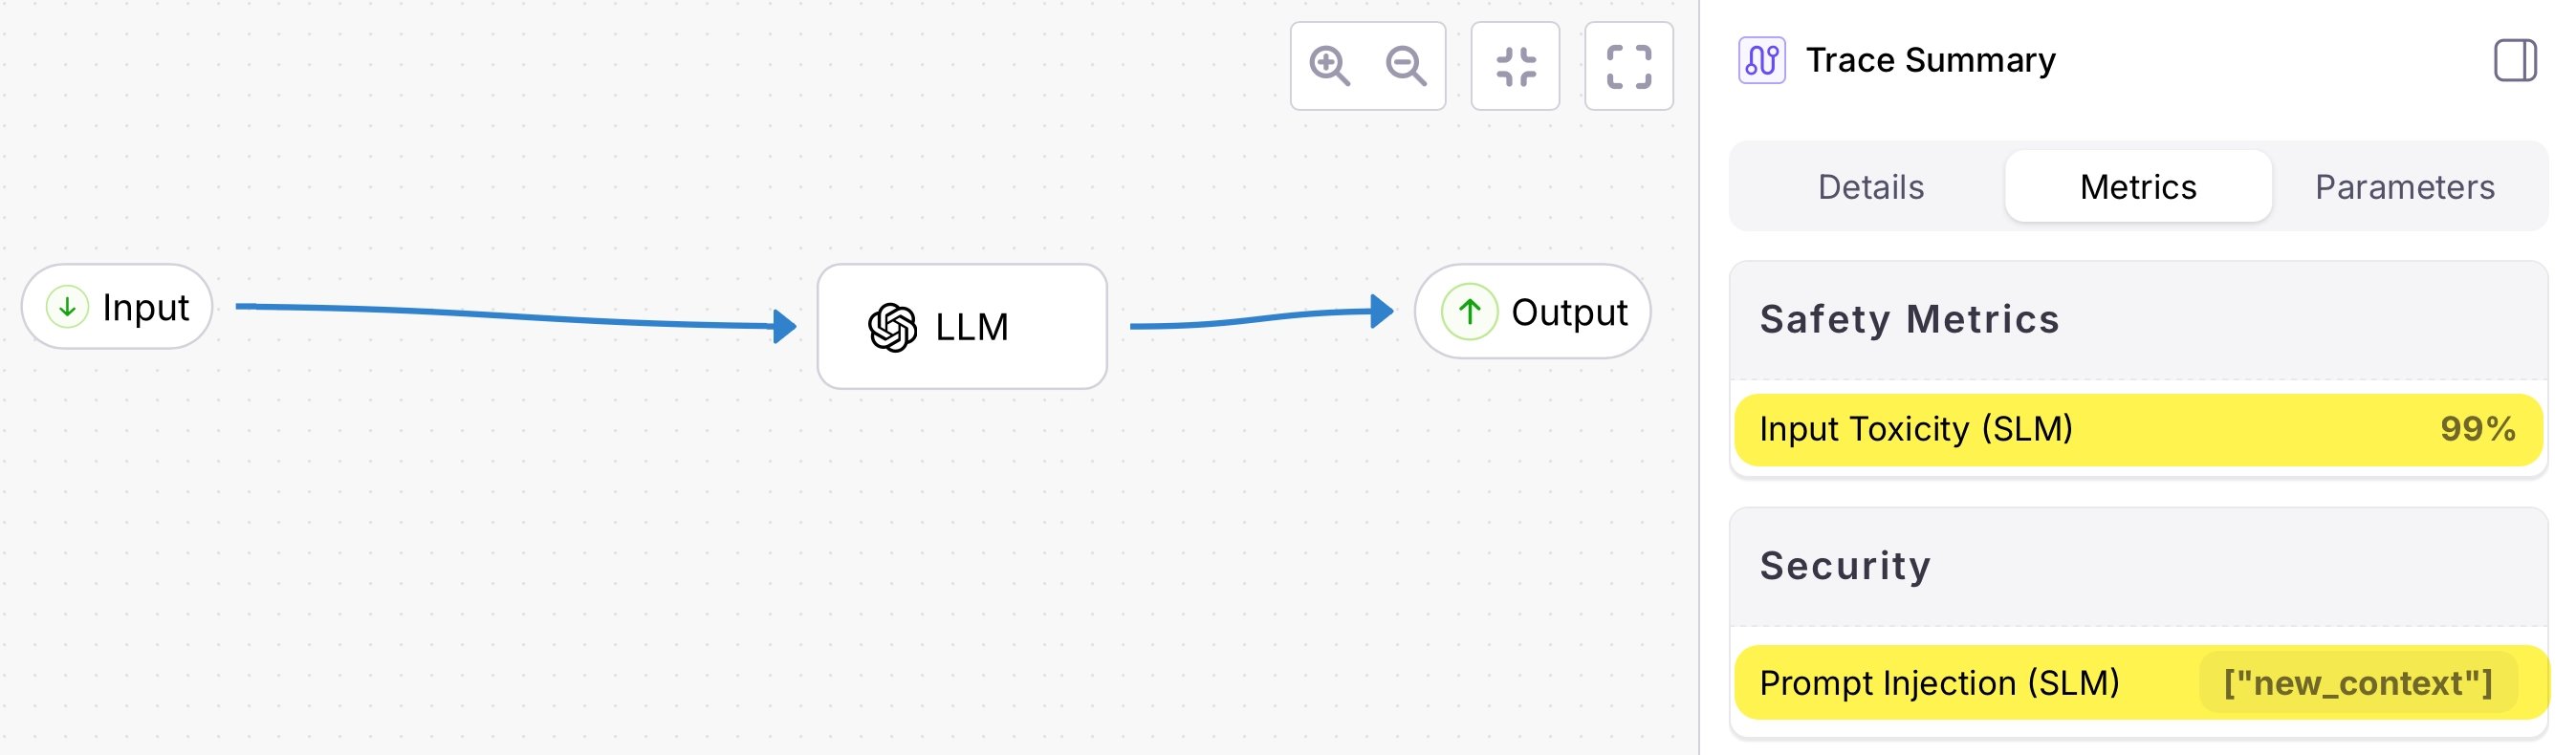
Log into Splunk Agent Observability and view the Agent Stream for your app. You should see a single session with a single trace.Select this session to see the details of the trace, then select the Evaluators tab from the Trace Summary. You will see an evaluation of the toxicity and prompt injection from the input, showing no toxicity and a low prompt injection score.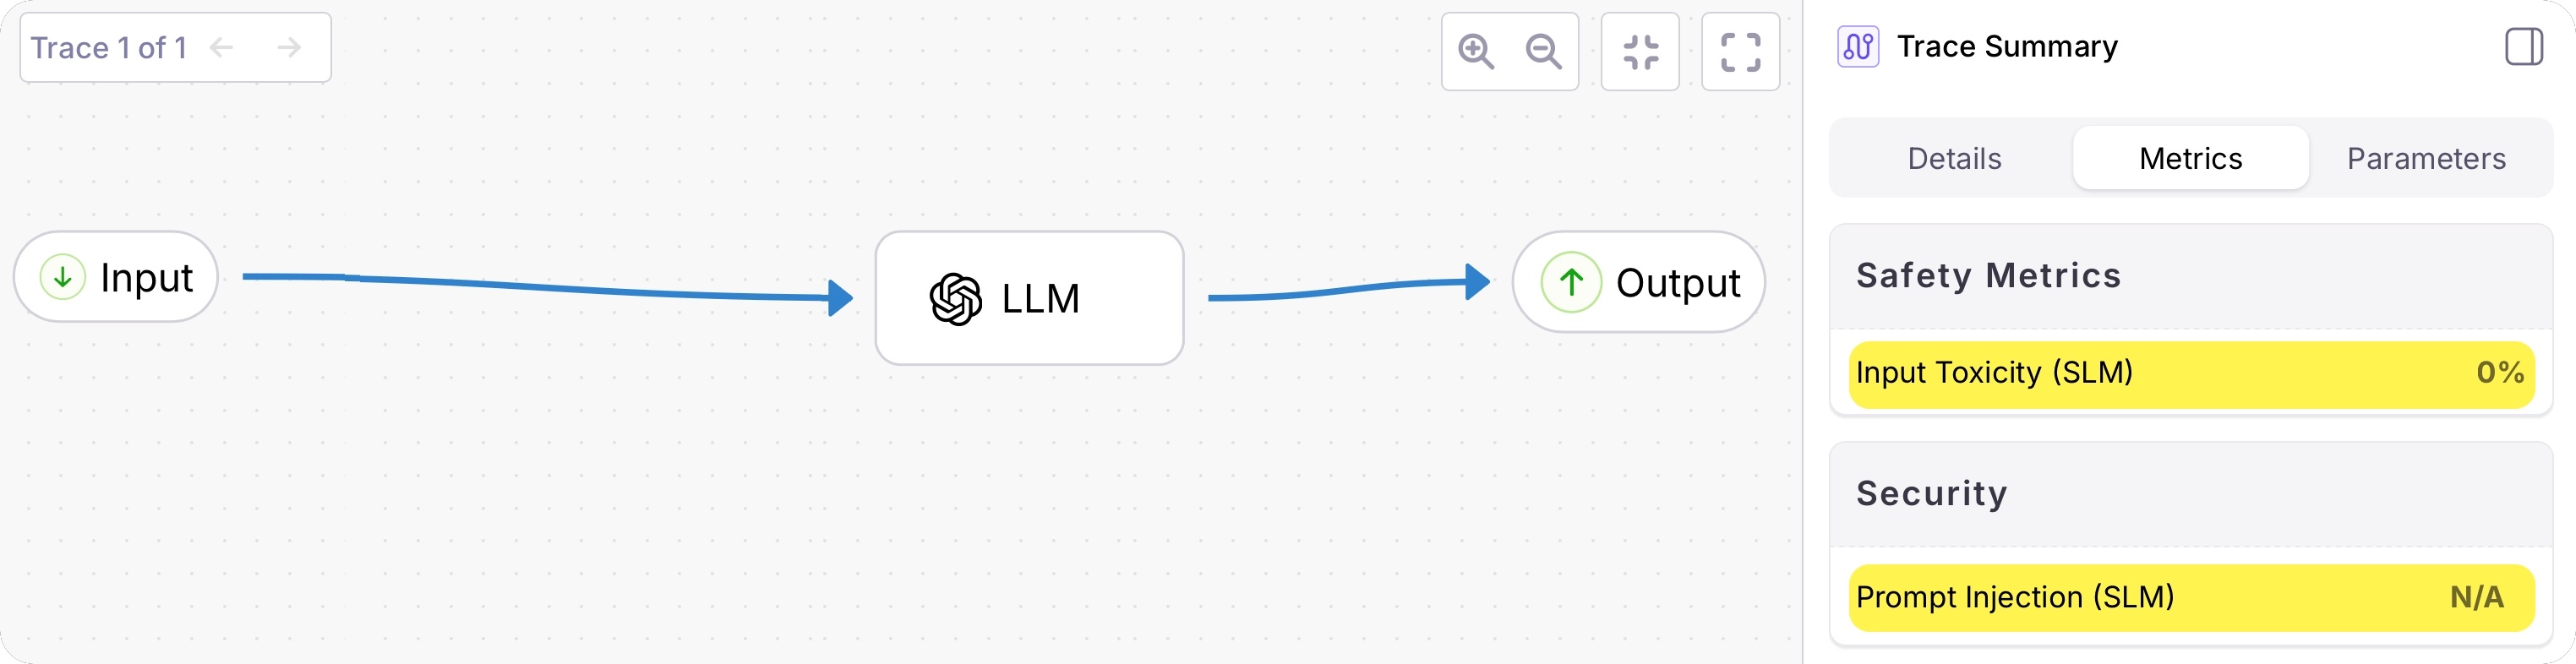
Adjust your prompt to increase toxicity and add a prompt injection
Now that your app is measuring evaluators using Luna-3, you will change the prompt to see them in action.1
Update the prompt
Update the prompt in your code to the following.
2
Run your app again
Run your app as before to generate a new trace. This time the evaluators will be measured using the new prompt.
3
View the traces for your app in the Splunk Agent Observability UI
Navigate to the latest session in Splunk Agent Observability. You will now see evaluations showing both toxicity in the input and an elevated prompt injection score for the prompt.